Analysis
AI Agents Made NFS Interesting Again
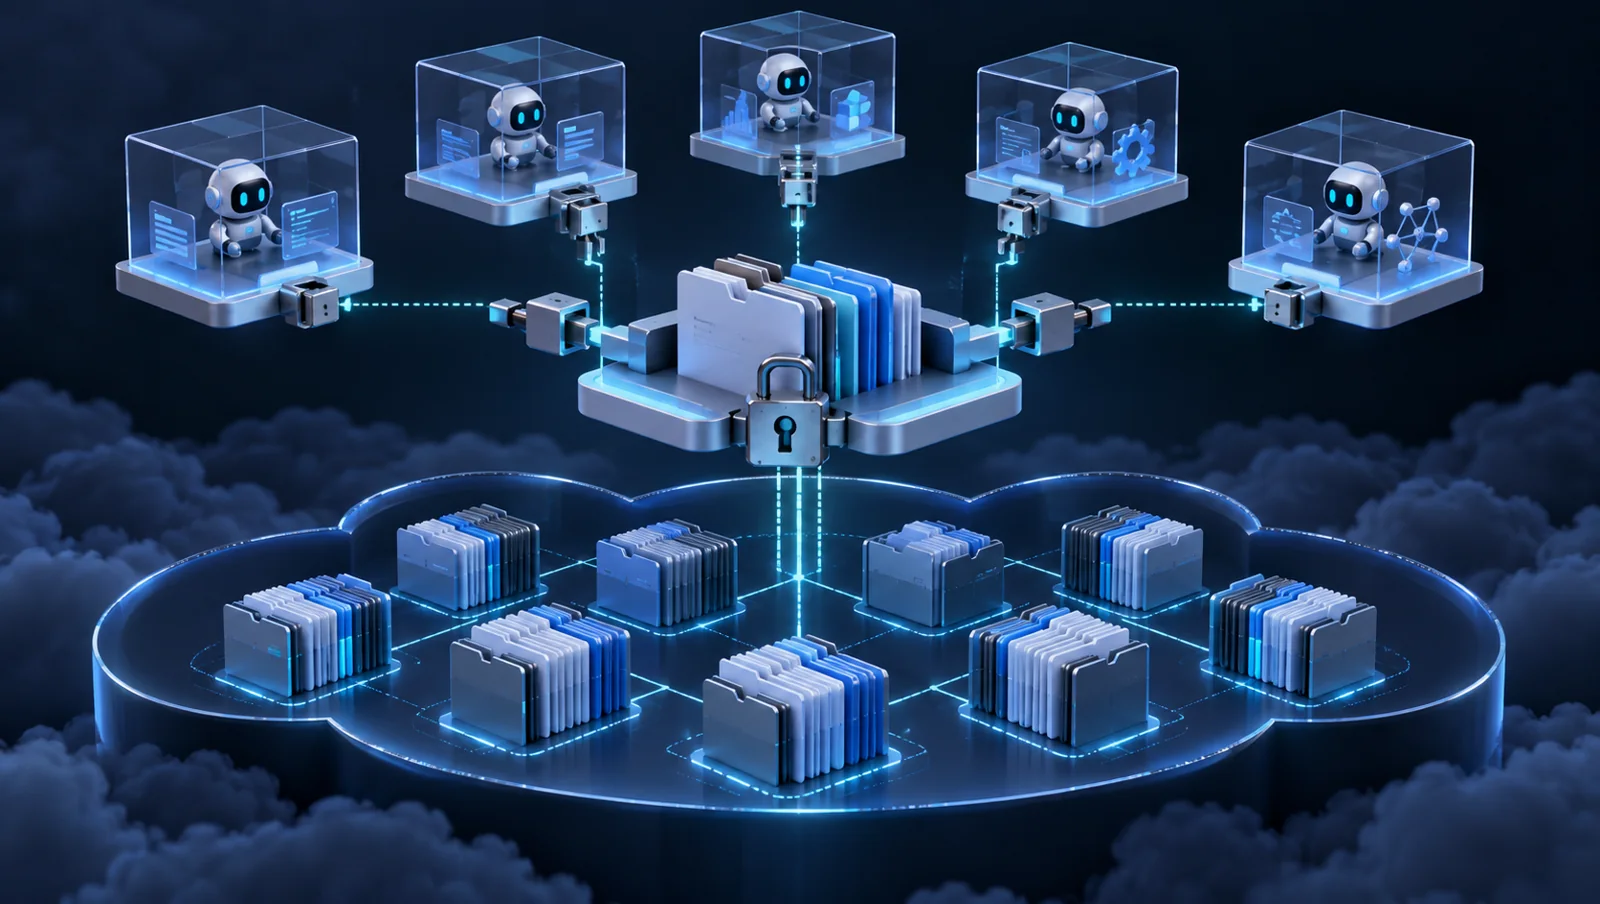
Google’s Filestore agent volumes give each agent a persistent POSIX workspace that can attach and detach in milliseconds. The storage is familiar—shared files, directories, permissions, and locks—but the lifecycle is built for sandboxes that appear, sleep, move, and resume.
That matters because an agent’s useful state often exceeds a chat transcript. It may include a repository checkout, generated artifacts, indexes, caches, and tool output that should survive the compute environment.
Persistence and isolation pull in opposite directions
A shared filesystem is convenient precisely because many processes can see it. An agent workspace often needs the opposite default: one task, one identity, one mount. Isolation must be enforced by the provisioning and export path, not by asking an agent to remain in its assigned directory.
Volume identifiers should be opaque, mounts should be created from current authorization, and a resumed sandbox should not inherit credentials merely because it inherited files. Snapshots and backups also become part of the data boundary.
POSIX semantics are useful for multi-agent work
Read-write-many access and file locking can support several agents working against one tree. They do not solve coordination. Two processes can make individually valid edits that produce a broken repository, and a lock around one file does not protect a cross-file invariant.
I would keep source control as the merge boundary, give each worker its own worktree or branch, and use shared storage for deliberate exchange points. The filesystem supplies primitives; the workflow still needs ownership.
Lifecycle is where the cost model lives
Google says customers pay for consumed capacity and can tier inactive data through lifecycle management. That is attractive only if volumes actually expire. Agent platforms generate abandoned checkouts, package caches, logs, and failed-run artifacts quickly.
Every workspace should have an owner, creation reason, last activation, retention class, and deletion policy. A user-visible recovery window is better than indefinite accumulation. Capacity alerts should distinguish active work from cold retained state.
Google has made the non-production capability broadly available while production general availability is allowlisted. I would test mount latency under concurrency, node loss, stale locks, permission changes, snapshots, and deletion before treating the claimed millisecond attachment as the whole storage story.