Analysis
Home Lab Backups with Ansible: Apply, Pull, and Restore
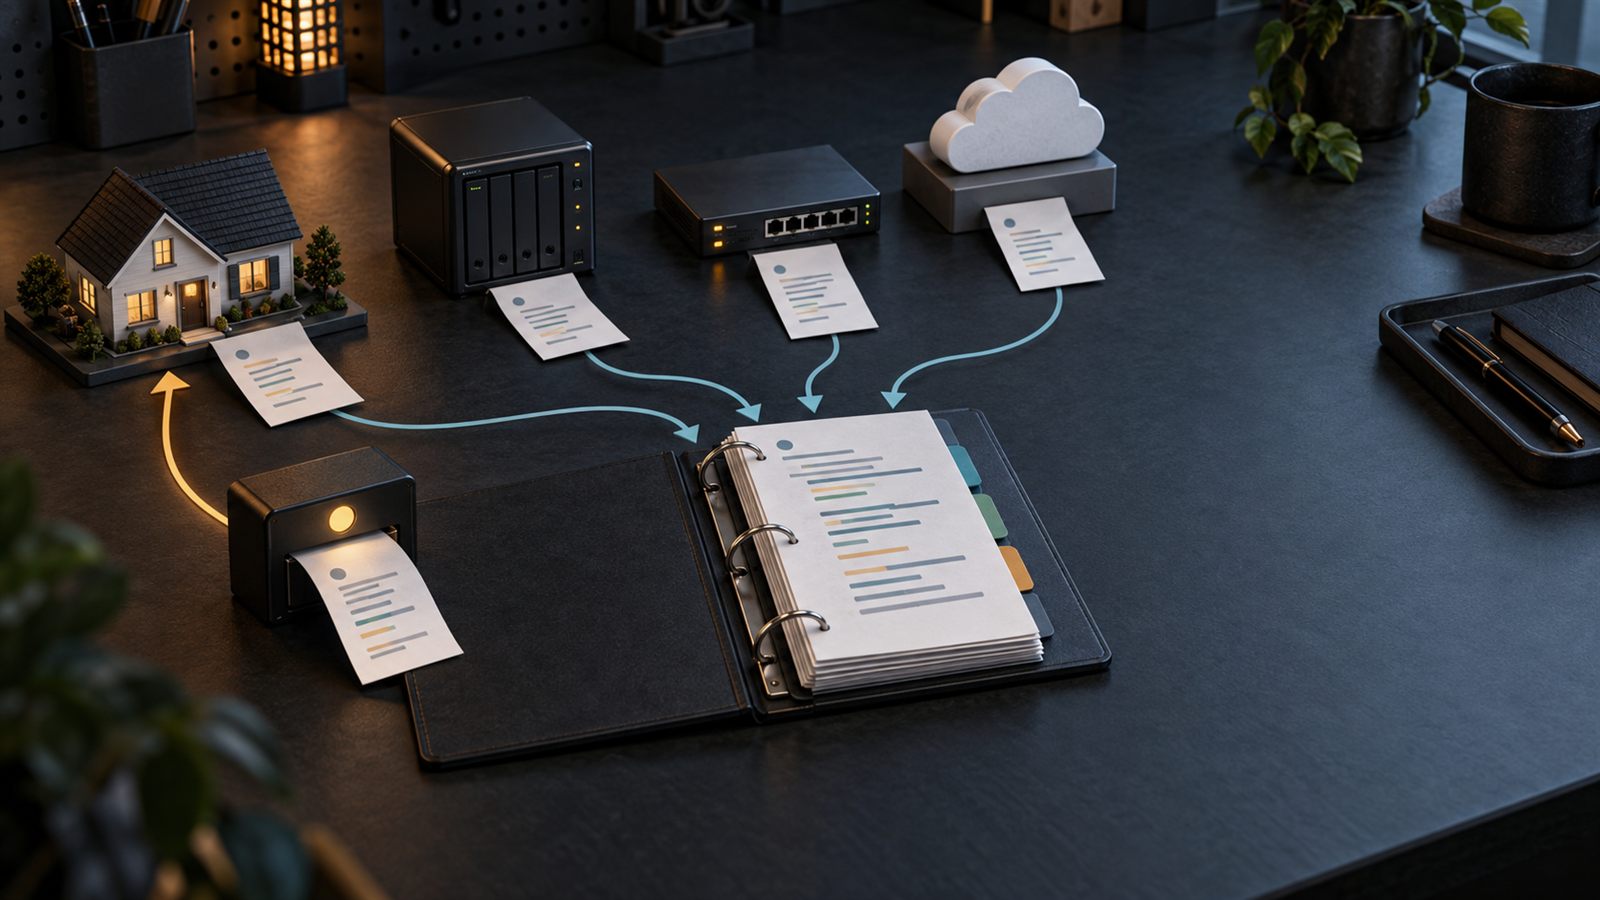
Home-lab configuration deployment, live-state snapshots, and restoration move data in different directions and should remain separate operations. Ansible can coordinate all three without pretending one playbook can rebuild every service.
What the repository actually covers
The inventory spans Linux hosts at home, a Home Assistant OS virtual machine, Docker services reached across another network, and public-facing servers. The operating systems and connection paths differ. Some machines accept ordinary SSH, one appliance is reached through its add-on environment, and remote systems sit behind tunnels.
I am not publishing the hostnames, addresses, tunnel ports, firewall allowances, or vault layout here. None of that would help a reader decide how to structure an Ansible project, and it would turn a useful article into an infrastructure map.
The important division is visible in three playbooks:
site.ymlcan change running systems.snapshot.ymlpulls selected configuration into the repository.restore.ymlpushes one selected Home Assistant file back.
That is the design I would keep. “Manage the home lab” is too broad to be a safe command. Apply, observe, and restore deserve different entry points.
I do not treat site.yml as a button
The main playbook contains routine roles, monitoring, network tunnels, snapshots, public-server configuration, and planned replacement infrastructure. Some legacy DNS and future-server plays carry Ansible’s special never tag so an ordinary run will not select them. That is a useful brake, especially because the legacy DNS roles could overwrite configuration owned by another management system.
It is still not enough for me to run the full file casually. My normal pattern is narrower:
ansible-playbook site.yml --syntax-check
ansible-playbook site.yml --check --diff \
  --limit one-host --tags one-role
ansible-playbook site.yml \
  --limit one-host --tags one-role
The first command catches parsing and structural errors. The second asks supporting modules to simulate changes and show a before-and-after diff on one target. The third is the actual change only after the target and role are obvious.
Check mode is not a transaction and it is not a promise. Ansible’s documentation says modules that do not support check mode may do nothing and report nothing. Conditional work based on a registered result may also behave differently in simulation. Diff output can reveal sensitive values, so I do not turn it on indiscriminately.
The snapshot runs in the opposite direction
The Home Assistant role uses ansible.posix.synchronize in pull mode. The running appliance is the source; the controller checkout is the destination. That direction is explicit in the task rather than hidden in a shell script.
The task also sets delete: false. If a file disappears from Home Assistant, the local snapshot does not immediately erase its previous copy. I prefer that failure mode for recovery, but it creates a different obligation: a file present in Git is not proof that it still exists on the appliance. A snapshot can preserve stale state.
The pull excludes the files that would make the repository look complete while making it unsafe or enormous: the Home Assistant database, logs, caches, media, runtime locks, cloud state, generated speech, credentials, certificates, and rotating integration files. Home Assistant’s own backup mechanism is responsible for the appliance state that the Git snapshot intentionally omits.
This is why I do not call the repository a Home Assistant backup. It is a readable history of selected configuration. A real recovery still needs an appliance backup, retained data, and a tested way to obtain both when the original host is gone.
Secret filtering needs more than Vault
The repository uses Ansible Vault for values that belong under source control. Vault is useful, but its own documentation is blunt about the boundary: it protects data at rest. Once a value is decrypted for a task, the playbook and its modules are responsible for preventing disclosure.
The snapshot roles therefore exclude private keys, certificate files, environment files, authentication databases, generated backup copies, and known secret-bearing configuration. The Docker snapshot path uses an extension allowlist and directory blocklist instead of recursively copying every bind mount.
One Home Assistant add-on writes a managed MQTT password into an otherwise useful YAML file every time it starts. The role currently pulls that file and then replaces the password in the controller copy with a redacted marker. That keeps the committed version clean, but the ordering is weaker than I want: plaintext reaches the checkout before the redaction task runs. An interrupted run could leave it behind.
I would improve that by sanitizing into a temporary path before the file reaches the tracked tree, or by excluding the whole file and generating a safe representation separately. “Redacted before commit” is not the same guarantee as “never written into the checkout.”
Two gaps the comments did not catch
The code review for this article found two mismatches between the intended snapshot design and the commands that actually run.
The documented size cap is missing
The Docker snapshot role says a maximum-file-size cap prevents large backups, media, or databases from slipping through its extension filters. The live task does not currently pass an rsync --max-size option. The extension and secret filters still do useful work, but the stated final guard is absent.
That is not a reason to distrust every snapshot. It is a reason to stop describing the cap as protection until the task enforces and tests it.
The scheduled commit covers fewer roots than the playbook
The snapshot playbook can pull Home Assistant configuration, container configuration from more than one machine, and selected DNS configuration. The scheduled wrapper only checks, stages, and commits two local roots. A successful pull from another source can therefore remain uncommitted and unpushed.
The wrapper also uses those same two roots when deciding whether an edit is already in progress. Its good safety check refuses to tangle a scheduled snapshot with changes in those paths, but it does not cover every destination the playbook can touch.
The fix is not to replace the list with git add -A. That would make the automation capture unrelated work. I would define the intended snapshot roots once, use the same list for the dirty-tree guard and commit, and add a test that fails when snapshot.yml gains a destination not represented by that list.
The scheduled wrapper has useful restraint
Before pulling anything, the wrapper checks for existing edits in its managed snapshot paths. If it finds one, it logs the conflict and exits without creating an automatic commit. That is the right instinct: a timer should not decide how to merge my unfinished work.
It then updates from the repository, runs the snapshot playbook, and does nothing when no tracked drift appears. When configuration changed, it commits only the named snapshot paths and pushes the result. Failure paths write a local log and can send a notification without embedding the notification credentials in the repository.
The repository documentation says this wrapper runs daily on the controller. I did not verify the live timer or its most recent successful run for this article. Source code proves the intended behavior, not that scheduling, network access, credentials, and the remote Git service all worked last night.
Restore is deliberately one file
The Home Assistant restore playbook requires a relative file name and refuses to proceed if the source is absent from the checkout. It copies that one file to the appliance with Ansible decryption enabled, preserves the previous remote version as a timestamped backup, runs ha core check, and restarts Home Assistant only when the file changed and restart was not disabled.
ansible-playbook restore.yml \
  -e file=automations.yaml \
  -e restart=false
I like the narrow blast radius. I do not like calling it transactional. The copied file is already active by the time ha core check runs, and the playbook does not automatically restore the backup if validation fails. The backup makes manual recovery possible; it does not perform the rollback.
The snapshot role excludes those timestamped backup files because they may contain pre-change plaintext secrets. That small connection between restore behavior and snapshot filtering is exactly why I keep both directions in the same repository.
What I would keep, and what I would fix next
| Part | Keep or change | Reason |
|---|---|---|
| Separate apply, snapshot, and restore playbooks | Keep | The direction and blast radius stay visible. |
| Explicit limits and tags | Keep | A whole-estate playbook should not imply whole-estate execution. |
delete: false snapshots |
Keep, with stale-file checks | Recovery is safer, but inventory truth becomes weaker. |
| Tracked-root list in the wrapper | Fix | Every pull destination needs the same guard and commit policy. |
| Claimed maximum-size filter | Fix | The task should enforce the protection described by its comment. |
| Post-pull credential redaction | Move earlier | Plaintext should not enter the tracked checkout first. |
| One-file Home Assistant restore | Keep, add rollback | Validation failure should return the known previous file automatically. |
When Ansible earns its place in a home lab
I would not introduce Ansible for one server that changes twice a year. A short, current recovery document may be easier to trust. Ansible earns its maintenance cost when the same boundary appears repeatedly: several machines need the same control, one change must be reviewed before reaching multiple targets, or a running configuration needs a predictable path back into version control.
The useful result is not a boast that everything is automated. It is knowing which state is declarative, which state is merely observed, which state is excluded, and which recovery step still requires a person.
The retired Home Assistant Compose article covers a case where automation preserved an unsupported installation model for too long. The Pi-hole and AdSense failure shows why resolver state has to be tested from each path, while the Snap-DNS article follows the same rule for secret ownership.
The repository and live-state boundary
The implementation details come from the current private home-lab checkout: its inventory, playbooks, snapshot roles, restore path, wrapper, and recent history. No secret values, private addresses, or access instructions are reproduced here. The command boundaries are cross-checked against Ansible’s official documentation for check and diff modes, Ansible Vault, and the synchronize module’s pull mode.
I inspected the current source and Git state, but I did not run the playbook, contact every inventory host, decrypt a vault, execute a restore, or verify the scheduled timer for this article. The two snapshot gaps are code-review findings, not failures reproduced against production.