Analysis
How I Deploy WordPress Changes Without WP-CLI—and Roll Them Back
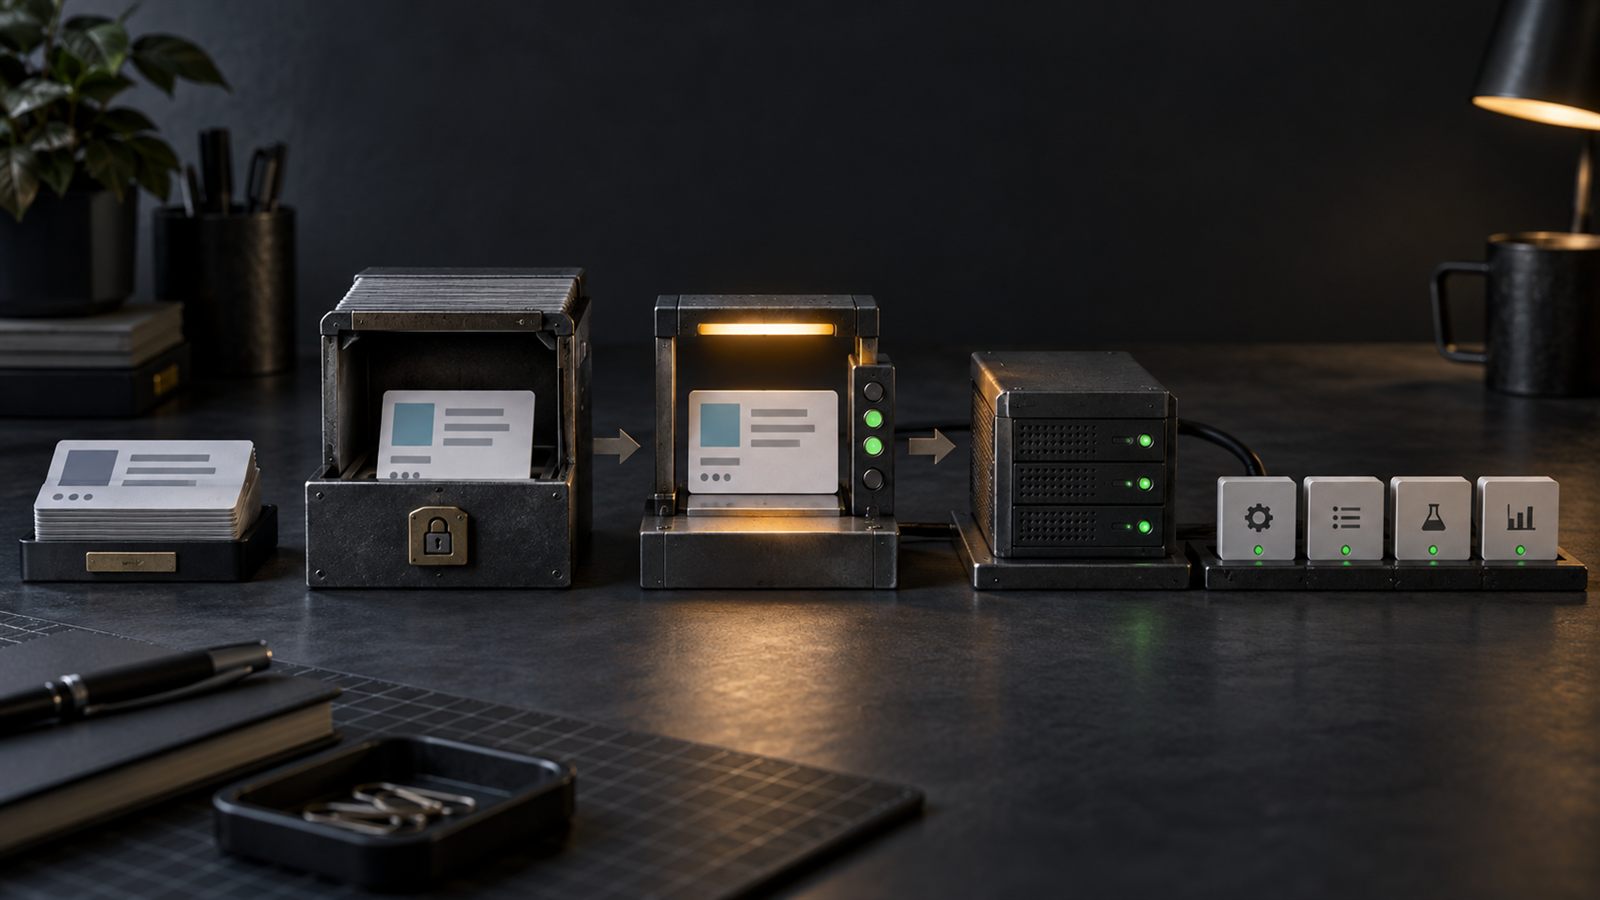
A safe WordPress database-backed deployment should prove its target, checkpoint the current state, write through WordPress APIs, deploy reusable code separately, and verify the public result. The absence of WP-CLI does not justify an unreviewable change.
Why I did not build a generic deploy script
The site started with broad bootstrap scripts that could replace the homepage, publish a batch of posts, and install theme or plugin files. Those were useful once. After the content changed, rerunning them became dangerous: the old payload could overwrite newer first-person copy, factual corrections, article images, and revenue plumbing.
I now treat those scripts as historical artifacts. The two most dangerous entry points refuse to run unless an explicit emergency override is present. That override is not part of a normal release. It exists for a reviewed disaster-recovery situation where replacing current state with the old bootstrap is actually intended.
Routine work gets a focused migration named for one article or one correction. The smaller script is repetitive by design. Repetition keeps its authority visible.
The database is authoritative, and that is a limitation
Article titles, excerpts, bodies, publication state, categories, authors, and media relationships live in the production WordPress database. The local directory contains the migrations that produced recent changes, not a complete export of the current site.
That distinction prevents a comforting but false claim: having the latest migration files does not mean I can reconstruct every row in WordPress. A content checkpoint can restore one post. A plugin backup can restore two PHP files. Neither replaces a tested database and uploads backup.
I still keep the migration sources because they make editorial changes reviewable before they touch WordPress. The file shows the exact body, target slug, category, image asset, and verification assumptions in one place. The database remains the running state; the migration is the change record.
Every migration starts by proving its target
A current article migration begins with several fail-closed checks:
- It must run from PHP’s command-line interface.
- It loads the production WordPress bootstrap rather than writing SQL directly.
- The active child theme must match the expected site.
- The exact slug and, for restored historical posts, exact post ID must exist.
- The post must be in the expected current or archive category.
- The prepared hero image must be readable before the content write starts.
If I point a restoration script at a post that is already current, it stops. If the slug resolves to the wrong category, it stops. If the active theme is not the one whose templates and metadata the tests expect, it stops.
This is intentionally different from an idempotent configuration role. A one-time content migration should not silently become a recurring content owner. Once it has changed the expected state, a second invocation is suspicious.
The checkpoint is written before WordPress changes
The script serializes the existing post fields and category IDs to a timestamped JSON checkpoint before calling a write API. The checkpoint is stored outside the public web root and receives owner-only file permissions.
Then the migration passes the original post ID, revised fields, and an explicit error-return flag to wp_insert_post() or wp_update_post(). WordPress documents that wp_insert_post() updates an existing post when the supplied array contains its ID. Asking for WP_Error output matters because a bare false-like result is poor deployment evidence.
I use WordPress APIs for category assignment, content filtering, hooks, cache behavior, and attachment relationships. A direct database update would bypass parts of that lifecycle and require me to reproduce assumptions WordPress already owns.
The checkpoint is still narrower than a transaction. The post write, attachment creation, metadata generation, and featured-image assignment are separate operations. If the final step fails, the earlier write may already be live. Recovery means reading the reported failure and deliberately restoring the checkpoint, not assuming an automatic rollback occurred.
Images are content, not an afterthought
Each current article needs a large featured image because the site exposes it in the visible article header, Open Graph metadata, large-image preview policy, and Article schema. The migration first looks for an attachment carrying the source asset’s unique marker. If it exists, the script reuses it. If not, it sends the prepared bytes through wp_upload_bits(), creates the attachment, generates responsive metadata, sets useful alternative text, and assigns the featured image.
WordPress documents wp_upload_bits() as creating a uniquely named file in the configured upload directory and returning either its file information or an error. That is more reliable here than copying an image into a guessed month directory and fabricating an attachment row.
The source marker keeps a migration retry from producing a second media attachment after a partial run. It does not deduplicate visually identical images under different filenames, so naming remains part of the release discipline.
Reusable behavior gets a separate backup
The site’s navigation, metadata, article template, archive privacy, calculators, AdSense loader, and related-reading maps live in must-use plugins. WordPress loads those plugins automatically, and its documentation notes an important tradeoff: must-use plugins do not receive ordinary update notifications. The operator owns the update process.
Before replacing a live must-use plugin, I copy the exact current files into a new timestamped directory. I lint the proposed PHP on the server, preserve the previous files, and only then install the new versions.
Content and behavior have different rollback units. If an article is wrong, restore its post checkpoint. If navigation or rendering is wrong, restore the previous plugin file. Bundling both into one mysterious “rollback” command would hide which state actually changed.
Publishing is the middle, not the finish
A migration returning a post ID and URL proves that WordPress accepted a write. The public page, crawler metadata, and unrelated articles still need checks of their own.
The public verification suite requests every managed route and checks the properties that have broken before:
- HTTP 200, one H1, one description, one canonical, and no accidental
noindex. - One AdSense publisher loader and the exact
ads.txtrecord on HTTP, HTTPS, apex, andwww. - Visible byline, Article schema, large-image permission, Open Graph dimensions, and a featured image at least 1,200 pixels wide.
- Every current post in the post sitemap and public REST collection.
- Archived posts absent from public queries and the archive index still behind login.
- Internal links returning 200 and historical replacements returning their intended permanent redirects.
- Three curated next reads for every current evidence-backed article.
Separate checks exercise the four calculators with 35 arithmetic and validation cases, inspect featured-media size and format, audit search-title and description lengths, verify six public GitHub referral links, and prove that affiliate output remains disabled until an account is active.
This is more testing than a single article needs. That is the point. A content change can expose a defect in the shared template, sitemap, REST filter, media metadata, or related map. The useful release boundary is the public site, not the row I intended to edit.
A real deployment from this morning
The restored Ansible article followed the complete path:
- I inspected the archived post and current private repository evidence.
- I wrote one migration for the original slug and post ID.
- I generated and compressed a 1600×900 editorial image.
- I added the article to one reading path and gave it three explicit related articles.
- I added a concise search title and article-specific regression assertions.
- I linted the PHP, backed up the two live reusable plugins, and ran the migration once.
- I verified 40 public URLs, 38 indexable snippets, 25 featured images, 25 related maps, calculator behavior, archive privacy, advertising plumbing, and inactive affiliate gates.
- I recorded the checkpoint and current counts in the revenue plan and recurring monitor.
That sequence is not fast because it has fewer steps. It is fast because each failure points at a bounded piece of state. A bad image does not require guessing whether the database changed. A related-map failure does not look like a deployment outage. A wrong article target stops before the write.
What this process still needs
| Current protection | Missing protection | Next improvement |
|---|---|---|
| Per-post JSON checkpoint | Complete database recovery | Automated database backup with a tested restore. |
| Timestamped plugin copies | Complete live-file inventory | Bring the canonical theme and plugin sources into one deployable repository. |
| Fail-closed migration checks | Atomic multi-step write | Add an explicit recovery handler for attachment or metadata failures. |
| Public HTTP regression suite | Rendered browser and assistive-technology coverage | Add focused visual and accessibility checks when the interface changes. |
| Manual release sequence | One recorded release result | Wrap lint, backup, migration, and verification without broadening target authority. |
I would not solve these gaps by creating one script that can rewrite the entire site. The next layer should compose the narrow migrations, backups, and tests while preserving their stop conditions.
My definition of a boring deployment
A boring deployment is not one where nothing can fail. It is one where the target is exact, the previous state is recoverable, the write result is checked, and the public behavior is verified before the change is called finished.
For this WordPress site, that means a small migration is safer than a stale universal publisher. It also means I cannot call the process complete until full database and live-file recovery are tested.
The Ansible home-lab article makes the same distinction between intended configuration, observed snapshots, and actual backup. The three-server MCP article shows why a health response is not enough, while the GitLab session article follows failures that only appeared at restart and teardown boundaries.
What this release process proves
The process and counts come from the current Hack Your World migration sources, live WordPress state, release checkpoints, and public regression output. WordPress’s official documentation covers wp_insert_post(), wp_update_post(), wp_upload_bits(), and the behavior and caveats of must-use plugins.
I did not perform a database restore, full server rebuild, automatic content rollback, load test, or browser-based visual audit for this article. The public checks prove the properties they assert; they do not prove every possible WordPress failure mode.